Chapter 2
The Engine: How Language Models Work
On this page
Every system in this book, from the plainest chatbot to a fleet of cooperating agents, is built around the same component: a large language model. You can use one productively while knowing nothing about its insides, the way you can drive a car without ever opening the hood. Building an agent is a different relationship with the machine. You are going to put this component in a loop, hand it tools, and let it make decisions while you are elsewhere; when it behaves strangely, “it’s magic” will not narrow down the bug. This chapter builds the minimum mental model an agent builder needs, intuition first, with no mathematics beyond arithmetic. We start with what the model fundamentally is (a next-token predictor), then take up its working memory (tokens and the context window), the way it writes (sampling, and why two runs differ), the way you steer it (prompting), the bridge from its text to real action (structured output and function calling), and finally the ways it reliably fails. Later chapters lean on every one of these ideas; none of them requires you to train anything.
LLMs as Next-Token Predictors
Finish this sentence: “The capital of France is —.” The word was in your mind before you decided to look for it. You did not consult a mental atlas, weigh candidate cities, or reason about geography; a lifetime of reading made Paris simply arrive. Hold on to that reflex, because it is the most accurate intuition available for what a large language model does. The model completes text the way you just did; unlike you, it has no other mode.
Mechanically, an LLM is a function: it takes in a stretch of text and produces, for every possible next token, a probability that it comes next. A token is a chunk of text from a fixed vocabulary—often a word, sometimes a piece of one or a punctuation mark; on average, think three-quarters of an English word. To write anything, the surrounding system picks one token from that ranked list, appends it to the text, and runs the model again on the now-longer text, one token at a time, over and over, until a stop condition fires. The scheme is called autoregressive generation (each new token is conditioned on everything before it, prompt and output alike), and one property of it will follow us through the whole book: the model never drafts its answer in advance. Its whole method is a local guess, repeated; it holds no plan and no outline in reserve (Figure 2.1). The next section examines tokens and the model’s working memory in earnest; the one after looks at how a token gets picked and why the choice varies.

Where does the guessing skill live? In the model’s parameters, also called weights—billions of numbers, fixed during training, that determine how input text flows through the neural network to produce those probabilities. The picture I find most useful is this: the weights are a lossy, compressed distillation of the patterns in everything the model read during training—grammar, facts, idioms, code style, the shapes of arguments. “Lossy” is the operative word. The model absorbed the shape of its reading and kept no archive of the text itself, which is why asking it to quote a source verbatim, or to recall a precise figure, is a gamble; we return to the consequences at the end of this chapter.
Two activities need to be kept firmly apart, because conflating them produces some of the most common misunderstandings about these systems. Training is the one-time, enormously expensive process of finding good values for the weights: the model is shown text, asked to predict the next token, and nudged slightly whenever it is wrong, across more text than any person could read in a thousand lifetimes. It is carried out by the model’s makers, on specialized hardware, before you ever see the thing. Inference is every use afterward: the weights are frozen, and the model simply runs your input through them. Everything you do with a model—every chat, every agent step—is inference. Two consequences follow, and you will design around both constantly. First, the model does not learn from your conversations; nothing you type changes a single weight, and what feels like memory within a session is only the growing transcript being re-read on every call. Second, the model’s built-in knowledge stops at a training cutoff (the point after which it saw no data). Events past the cutoff are simply absent, and the model will not reliably announce the gap; it answers from stale knowledge with exactly the confidence it brings to fresh. Anything time-sensitive must arrive in the prompt, or be fetched by a tool.
Training itself happens in stages, and the stages explain a puzzle you would otherwise trip over. The first and costliest stage, pretraining, is pure next-token prediction over a vast, broad corpus—web pages, books, code. Its product is a base model: fluent, widely knowledgeable, and strangely useless as an assistant. Chapter 1 mentioned, in passing, that such a model may answer a question with more questions, and promised that this chapter would show why. You now hold every piece of the explanation; assemble it before reading on. A base model only continues text, so when you hand it “What are three ways to make this query faster?”, it looks for a plausible continuation—and in the wild text it studied, one question is often followed by others like it. A list of further questions is a perfectly likely reply. The base model is doing its job perfectly; the job is continuation.
Post-training is the further stage that turns that raw continuer into the assistant you have actually met, and it is what Chapter 1’s “models learned to take instructions” referred to. Two moves matter for our purposes. Instruction tuning trains the model on curated pairs of instruction and good response, teaching it that a question deserves an answer rather than more questions. Preference tuning—the best-known form goes by RLHF, reinforcement learning from human feedback—has people (or models trained to mimic their judgment) rank competing answers, and adjusts the weights toward the kinds of answers people prefer: more helpful, more honest, better mannered. Post-training is where the familiar assistant persona comes from, and it is a comparatively cheap coat of paint on the enormous pretrained core.
Be equally clear about what post-training does not buy. It adds no new knowledge, and it does not remove the tendency to fabricate. A memorable framing from one widely watched lecture on the subject: post-training does not stop the model from dreaming; it shapes the dreams into helpful-assistant-shaped dreams.1 The “dreaming” framing is Andrej Karpathy’s, from his widely circulated talks and commentary on large language models (e.g. “Intro to Large Language Models”); it is rendered here as a paraphrase, not a verbatim quote. Underneath the manners, the engine is unchanged: a next-token predictor, optimizing for the plausible continuation. Plausible and true are correlated. The correlation exists because the training text was mostly written by people describing a real world—but the two part company exactly where the model lacks the fact, and at that moment the machinery produces the most plausible-looking string instead of stopping. Fluent first, correct second.
For an agent builder, the corollary I most want you to keep is that the model’s knowledge lives in two places of unequal reliability. Parametric knowledge sits in the weights: frozen at the cutoff, approximate, impossible to cite. Context knowledge is whatever text is in front of the model right now: fresh, inspectable, checkable. The model is markedly more reliable when the facts it needs are in its context than when it must dredge them from its weights, and that asymmetry seeds half the engineering in this book. Retrieval, tools, and the whole discipline of context engineering in Part III are, at bottom, ways of moving load-bearing facts out of the first place and into the second.
So this is the engine: superb at language-shaped work—drafting, rewriting, summarizing, translating, explaining, transforming code—and unreliable as a database or a calculator, with a confidence dial that is permanently stuck on high. An agent will ask this engine to make decisions, many in a row, about a world it can only see through the keyhole of its context. The keyhole is where we go next.
Tokens and the Context Window
Everything the model knows in the moment arrives through that keyhole, so we had better measure it. Chapter 1 needed little more than a definition of the context window: the bounded stretch of text a model can consider in a single call. This section fills in the picture, and the place to start is the unit the window is measured in, because nearly every limit you will hit while building—the ceiling on what the model can see, the bill at the end of the month, the pause before an answer begins—is denominated in tokens. The previous section offered a napkin version: a token is a chunk of text, on average about three-quarters of an English word.2 The three-quarters-of-a-word rule (equivalently, about four characters per token in English) comes from OpenAI’s help-center note “What are tokens and how to count them?”; it is a rough average for English prose, not a constant. The napkin version hides a real design problem, and the solution to that problem explains several behaviors that would otherwise look like plain stupidity.
The design problem is this. A model needs a fixed vocabulary: a finite menu of chunks out of which every possible input and output will be assembled. Suppose the menu were whole words. The vocabulary balloons—love, loves, loved, lovingly each need their own entry—and the first typo, invented name, or word coined after training has no entry at all. Suppose instead the menu were single characters. Now nothing is unrepresentable and the vocabulary is tiny, but every text becomes an enormously long sequence of nearly meaningless units. Production models settle on the compromise between the two, called subword tokenization: a fixed vocabulary of chunks, far larger than an alphabet and far smaller than a dictionary of every word form, in which common words travel as single tokens while rarer ones are assembled from pieces, so that annoyingly might become annoying + ly, and unhappiness might become un + happi + ness.3 Hugging Face’s tokenizer documentation (“Summary of the tokenizers”) describes the standard subword algorithms—BPE, WordPiece, Unigram—and illustrates them with splits like these. For a hands-on deep dive, Andrej Karpathy’s lecture “Let’s Build the GPT Tokenizer” constructs one from scratch and tours the odd behaviors it causes. Frequent strings are represented cheaply; any string at all can be represented by falling back to smaller pieces.
The machine that does the chopping, the tokenizer, deserves a short paragraph, because it is far simpler than people assume. It is a fixed, deterministic lookup table, built once alongside the model and frozen for the model’s whole life. On the way in, it converts your text into a list of integer IDs; on the way out, it converts the model’s chosen IDs back into text. Notice what this implies: the network never sees your characters. From where the model sits, the world is a sequence of numbered chunks, and whatever happens inside a chunk was erased before the model ever got involved.
That erasure is testable, and I recommend running the test yourself. Ask a model how many times the letter r appears in some ordinary word, or ask it to spell a word backwards. Models have stumbled over exactly such questions for years, sometimes comically, in the same conversation where they solve a genuinely hard problem. The pattern stops looking absurd the moment you hold the tokenizer in mind: the word arrived as one or two opaque chunks, and the letters inside a chunk are precisely the information the lookup table threw away. To count them, the model must reconstruct the spelling from whatever it absorbed about that word during training—a memory task, and an unreliable one. (By the time you read this, the model you try may well pass; such gaps get patched by training, or the model quietly reaches for a tool. The mechanism the failure exposes is still underneath.) Digits tell the same story: in at least one widely used tokenizer, 520 is a single token while 521 splits into 5 + 21,4 Which particular numbers split is an arbitrary fact of each tokenizer’s training. In the byte-pair tokenizer of the GPT-2/GPT-3 generation, for instance, 520 is one token while 521 becomes 5 + 21; later tokenizers tend to keep short numbers whole but still chunk longer ones irregularly. The point is that some numbers split, and the model cannot see inside a chunk. so the model does arithmetic over chunks that ignore the number system—one reason its mental arithmetic is shakier than its fluency suggests. The lesson generalizes: the model’s world has a grain, and the grain is the token.
Three consequences of tokenization matter to a builder more than its internals. First, the token-per-word ratio drifts with content: code, numbers, and structured data tokenize less efficiently than prose, so a page of JSON costs more tokens than a page of essay. Second, most tokenizers were trained predominantly on English, so the same meaning can cost several times as many tokens in another language—one analysis found Burmese running at roughly eight times the token count of equivalent English, a figure I cite as an illustration of the disparity, not a constant5 Aleksandar Petrov et al., “Language Model Tokenizers Introduce Unfairness Between Languages,” NeurIPS 2023 (arXiv:2305.15425), which measures disparities up to roughly fifteen times across a range of tokenizers; the roughly-8× figure for Burmese is a conservative illustration of how wide the gap can get for languages underrepresented in tokenizer training.—which has plain cost and fairness consequences if your users write in many languages. Third, distinctions you would never think about are real to the tokenizer: the same word with and without a leading space, or capitalized and not, can be entirely different tokens. The practical habit that follows from all three: when a count matters, measure your actual text with the provider’s own tokenizer or counting endpoint. Every model family chops text differently, so a count borrowed from one is only an estimate for another. (I notice that nearly every number in this section arrives wrapped in “roughly.” With tokenizers, roughly is the honest register.)
Now the window itself. The picture I will use for it, here and for the rest of the book, is a desk: the work surface on the model’s side of the keyhole, on which everything the model consults during a single call must fit at once. Spread across that desk, in a typical agent call, are your standing instructions, the whole conversation so far, the definitions of every tool the agent might use, the full text of every tool result that has come back, whatever documents were fetched for the task—and the answer the model is writing, which lands on the same desk as it grows. One token budget covers them all. There is no drawer, no shelf, no second desk. If a fact is on the desk during this call, the model can use it; if it is anywhere else in the universe, then for the duration of this call it does not exist.
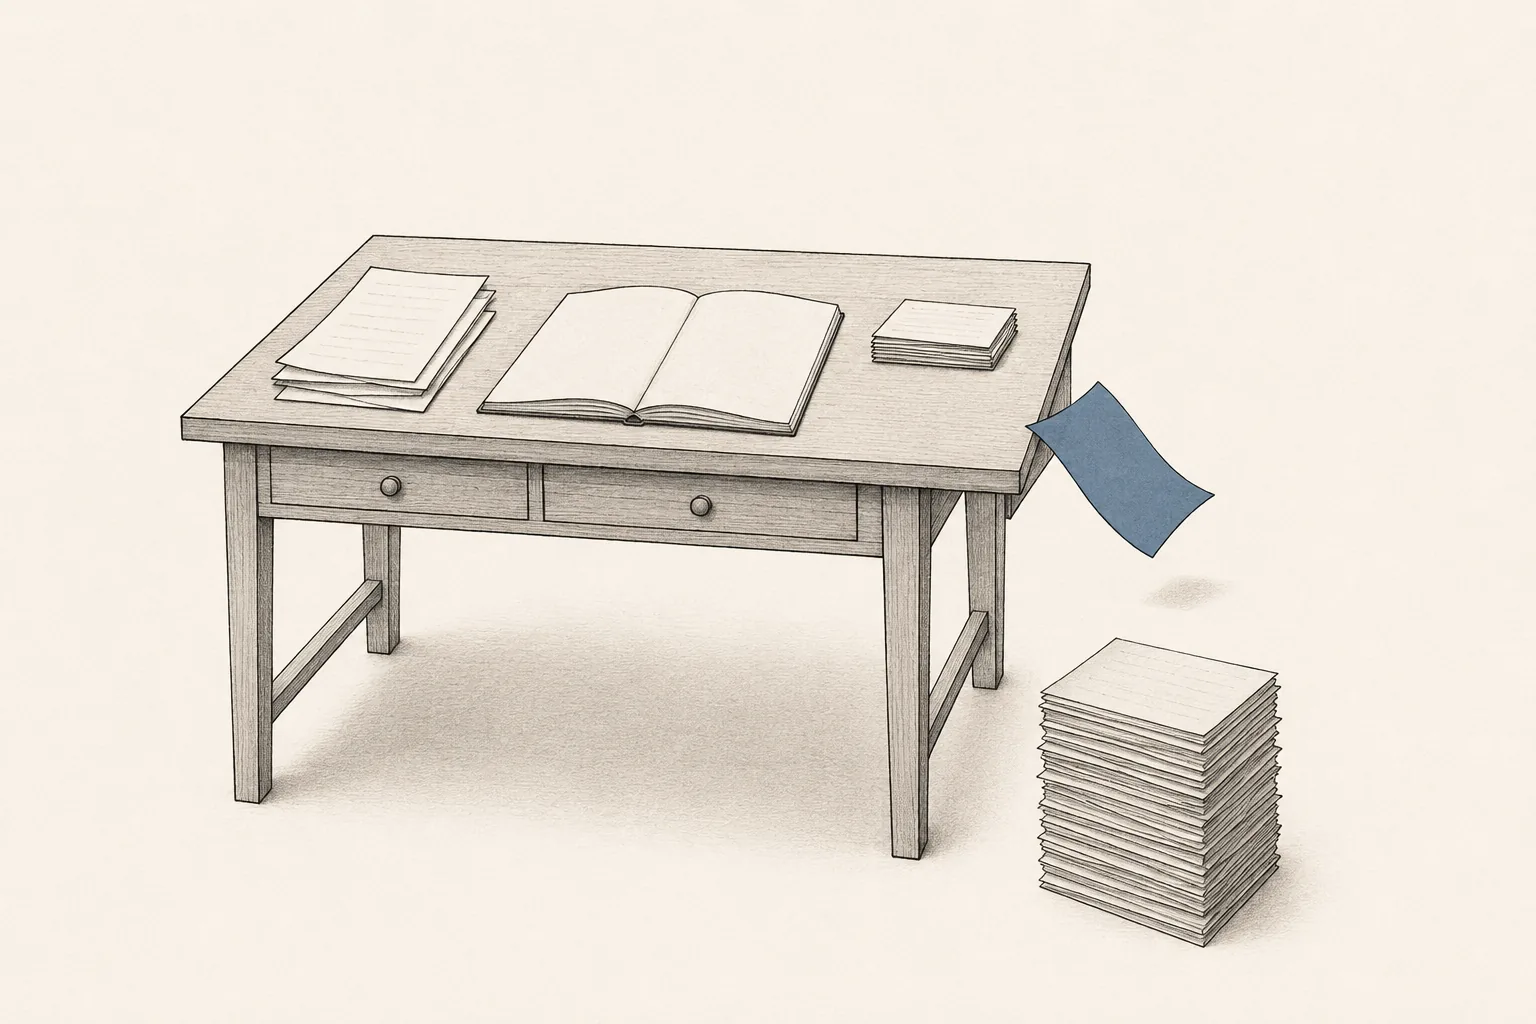
The desk is also swept bare between calls, and here the metaphor needs its honest boundary: your working memory carries into the afternoon, while the model’s does not survive to the next request. An LLM API is stateless (each call starts from nothing), which gives the previous section’s point about memory its operational shape: to continue a conversation, the surrounding software lays the entire transcript back on the desk every turn, the way you might reread a whole email thread before replying to its newest message. The habit is harmless at three messages and ruinous at three hundred. A sketch, with made-up but realistic numbers: standing instructions, 500 tokens; conversation so far, 8,000; two fetched documents, 40,000; the latest tool result, 3,000. The model reads more than fifty thousand tokens before writing a word, you pay for every one of them, and next turn the pile is larger still, because this turn has joined the history. (Providers soften the cost of re-reading an unchanged pile with caching, one of the main levers of Chapter 19.)
What happens when the pile no longer fits? Nothing graceful. Depending on the API and the software in between, the request may be rejected outright with an error; or the input may be truncated—cut down until it fits, usually by dropping the oldest turns, often without telling anyone; or a framework in the middle may summarize the history before sending it. The outright error is the kind outcome. Silent truncation is the treacherous one: the call succeeds, the answer comes back fluent, and the model has been reasoning over an amputated transcript from which your original instructions may have quietly fallen. From the outside this looks like a model that got dumber overnight, and it burns debugging hours accordingly. When a long session starts “forgetting,” check for overflow before you blame the model. (A cousin of this surprise: input and output share the window, but many models separately cap a single response at a much smaller figure. An answer that stops mid-sentence usually hit the output cap.)
One more property of the desk, and Chapter 1 already let it slip: even what fits is used unevenly. On long inputs, models recall material near the beginning and near the end markedly better than material buried in the middle—the compass called such a fact half-forgotten, and the research literature calls the effect, aptly, “lost in the middle.”6 Nelson F. Liu et al., “Lost in the Middle: How Language Models Use Long Contexts,” Transactions of the Association for Computational Linguistics (2024). Accuracy on long-context tasks was highest when the relevant passage sat at the start or end of the input and sagged when it sat in the middle. A bigger desk therefore solves less than it appears to: the edges stay sharp while the middle grows. Here is the mechanical basis of the book’s second bearing, the scarcity of context, and the craft it forces—deciding what deserves the desk at all—fills Part III, beginning with Chapter 7.
Even when everything fits and sits where recall is strong, the pile is never free. Tokens are the unit of your bill in both directions, input and output. They are the unit of your wait, too: before the model can emit the first token of its answer it must read the entire pile—a phase called prefill—and in the standard architecture the cost of that reading grows steeply with length, roughly on the order of its square. A bloated context makes the agent slower to start answering and more expensive on every single call, whether or not the extra material helps. So the window is a ceiling, not a target; the useful question is the smallest desk that actually holds your task.
For a chatbot, these are background facts. For an agent, they are daily weather: the loop appends to the desk on every step—reasoning, tool call, tool result, again and again—and nobody curates the pile unless you build the curation. Twenty steps in, the transcript is heavy with stale directory listings and half-relevant page dumps, the instruction that actually matters sits mid-pile where recall sags, and each further step reads, and bills, the whole accumulation. The desk is now measured. What remains of the mechanics is the writing itself: how the model picks one token from its ranked guesses, and why two identical runs of your agent will not behave identically. That is next.
How Text Is Generated
Hand the model the fragment “The cat sat on the” and, as the opening of this chapter described, back comes a ranked list: a probability for every token in the vocabulary. Say the top of that list reads mat at 0.42, floor at 0.18, sofa at 0.13, rug at 0.09, with the last scraps of probability scattered across thousands of also-rans. (The numbers are invented; the shape is typical.) Now the question this section turns on, and I would like you to commit to an answer before reading further: which word does the model write? The answer that feels obvious is mat—take the best guess; why would a machine do anything else? Yet for most systems you will ever call, that answer is wrong. By default, the machinery rolls dice.
The step in question—turning a ranked list into one chosen token—is called decoding, and the obvious strategy has a name: greedy decoding, always take the single most probable token. Greedy is deterministic, cheap, and sounds like the responsible choice. It also produces text with a well-documented ailment: flat, oddly repetitive prose that can lock into loops, the same phrase surfacing again and again.7 Ari Holtzman et al., “The Curious Case of Neural Text Degeneration,” ICLR 2020. The paper documented how maximization-style decoding degenerates into repetition and introduced nucleus (top-p) sampling as a remedy. The reason is counterintuitive enough to spell out. Human writing keeps taking small risks—an unexpected adjective, a fresh turn of phrase—while a decoder that never gambles drifts into the blandest corner of the language and then circles it. The locally safest word, chosen every time, composes into a globally mediocre passage.
The alternative, and the default nearly everywhere, is sampling: draw the next token at random, weighted by the model’s probabilities. mat wins the draw 42 times in a hundred; rug gets its turn about nine times in a hundred. The picture to keep is a weighted lottery, run once per token: the model prints the odds, and the decoder draws a ticket. Every fluent, natural-sounding answer you have admired was assembled this way, one draw at a time. And a property of your future agents is being fixed here, before any agent exists: variability is designed in. Two identical requests can draw different tickets, and the moment one draw differs, the two texts part ways for good, because every later token is conditioned on the earlier ones.
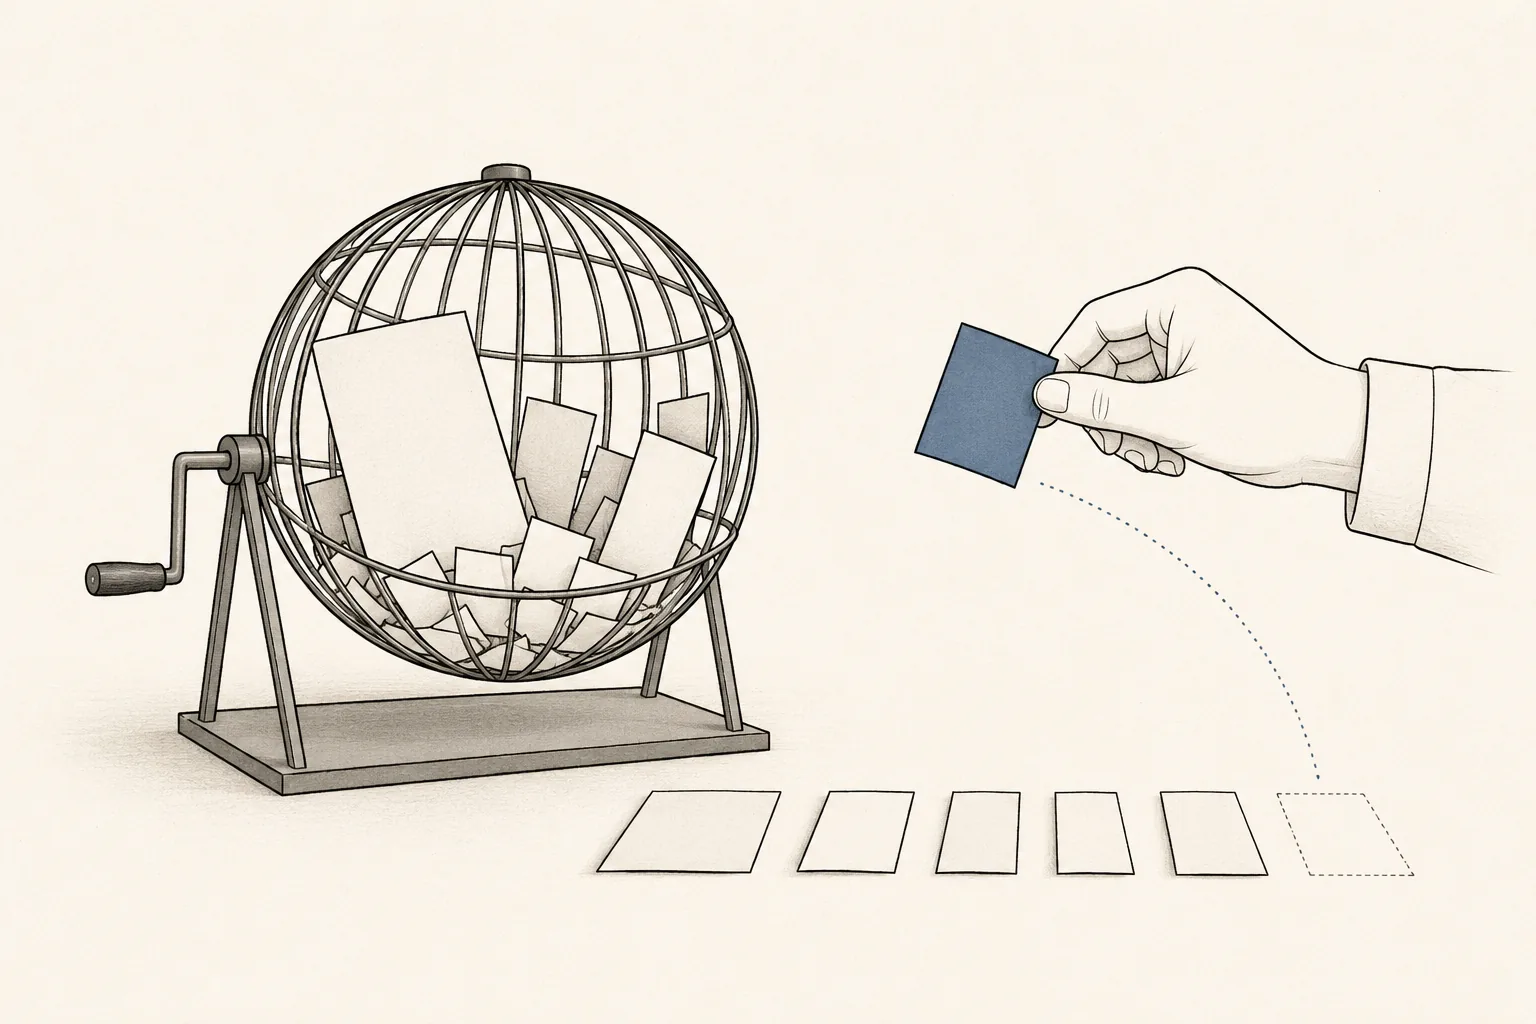
Between greedy and wild there are knobs, and they all do one thing: reshape or trim the ranked list before the draw. All of them operate downstream of the prediction: the ranked list is fixed, and the knobs govern only how you pick from it. Temperature is the sharpness dial. Turned down, it widens the gap between favorites and long shots until, at zero, the top token wins every draw and you are back to greedy; turned up, it flattens the field, gives the long shots real chances, and eventually dissolves the text into noise. Notice what the dial trades: low temperature buys consistency, high temperature buys variety, and correctness sits at neither end—a wrong answer can be drawn confidently at any setting.
The other two common knobs trim the field instead of reshaping it. Top-k keeps only the k highest-probability tokens and discards the rest—simple, but k is a fixed pool size, and the number of genuinely plausible continuations varies wildly from one moment to the next. Top-p (also called nucleus sampling) repairs that by keeping the smallest set of top tokens whose probabilities add up to at least p: after “The capital of France is,” the pool may hold a single token; after “My favorite food is,” it may hold dozens. The pool sizes itself to the model’s own confidence, which is why top-p is a common default. The practical guidance is short. Choose the setting by task—low temperature for anything a program will parse or a test will check, higher for brainstorming and drafting—and adjust one knob at a time, since several of them squeeze the same distribution.
Generation also has to end, and it ends in one of three ways. The model can emit a special end-of-sequence token—training taught it to say “I am finished” in vocabulary form—which is the happy path. A hard maximum-length cap can cut the output off mid-thought; the previous section met this as the answer that stops mid-sentence. Or a caller-supplied stop sequence (a string you designate in advance, often a delimiter) ends generation the moment it is produced. One habit to build now: APIs generally report which of these ended the response. Read that field. A reply truncated by the length cap looks exactly like a model failure, and is actually a budget you set.
Now the question the previous section left hanging: why two identical runs of your agent will differ. The first source of variation is in plain sight. Sampling is a lottery, so any temperature above zero means the same prompt can draw different tickets, fork, and never rejoin. This source is intentional and fully under your control: set temperature to zero, and the draw becomes deterministic. In theory.
Here is a prediction exercise for the intuition you now have. Suppose one prompt is sent to a hosted model a thousand times at temperature zero (greedy decoding, no lottery). How many distinct answers should come back? The arithmetic in your head says one. When a research team actually ran this experiment, they got eighty. All one thousand completions were identical for the first 102 tokens; at token 103—the sentence had reached a biographical subject’s birthplace—992 of them phrased it one way, 8 another, and from that fork the transcripts spread.8 Horace He et al., “Defeating Nondeterminism in LLM Inference,” Thinking Machines Lab (2025). The experiment: 1,000 temperature-zero completions of “Tell me about Richard Feynman” produced 80 unique outputs, identical through token 102 and first diverging on the birthplace phrase (“Queens, New York” versus “New York City”). The figures illustrate the phenomenon, not a constant of nature. The popular explanation blames rounding error on parallel hardware, and it is incomplete. The fuller account concerns a property called batch invariance, or rather its absence. A hosted endpoint serves many customers at once and batches their requests together for efficiency; the size of the batch rises and falls with traffic; and the low-level numeric routines inside the model can return minutely different results at different batch sizes. Minute is enough. When two tokens sit nearly tied at the top of the ranked list, a wobble in, say, the sixth decimal place decides the winner, greedy faithfully picks it, and the text forks. From your side of the API, the deciding input is how many strangers happened to be querying the same servers at the same instant—an input you cannot see, control, or replay. Batch-invariant versions of those routines exist and do fix this, at a cost in serving speed; at the time of writing they are the exception. So treat temperature zero as a strong preference, honored almost always—and remember that “almost always,” rolled at every token of every step, leaves room for surprises.
What should a builder do with all this? Three habits. First, give up exact-string reproducibility as a foundation: write tests that assert properties of the output—it parses, it names the right customer, it passes the checker—because a test that asserts byte-for-byte equality will flake in ways that waste your weeks. Second, expect the failure you saw once to resist reproduction on demand; that is a fact about the infrastructure, and Chapter 15 builds the recording tools that make such failures debuggable anyway. Third, feel the agent-shaped consequence: an agent runs this lottery at every token of every step, and each step’s output becomes the next step’s input, so run-to-run variation compounds along the loop—same task, different path, both plausible. The response to this that has aged well in the field is to make the outcome checkable rather than the output identical: the verifiability bearing from Chapter 1, arriving now with its mechanical justification.
So the machine writes by lottery, and the lottery explains the variety. The next question is steering. If the weights are frozen and the dice are indifferent, the only lever left is the text you lay on the desk—what to say, in what order, and what to show by example. That lever is the next section.
Prompting Fundamentals
Count the levers you actually hold over this machine. The weights are frozen; nothing you do at inference time will change them. The sampling knobs of the previous section adjust how a token is drawn from the ranked list, never what the model predicted in the first place. Everything else comes down to a single instrument: what you choose to write. That text is the prompt, and the craft of writing it well—prompt engineering, a grand name for a practice that is part writing and part experiment—is the basic steering skill on which everything agentic rests. Its fundamentals fit in this one section, and they are worth the reread even if you have prompted models for years: an agent assembles a fresh prompt at every step of its loop, so a weakness here is a weakness repeated throughout everything you build later.
Start with the anatomy. Modern chat models take a list of messages, each tagged with a role, and three roles are nearly universal (their exact names and wire formats vary by provider; treat any specific syntax as a vendor detail). The system message carries the standing instructions: who the model is supposed to be, what it may and may not do, and the shape its answers must take. It is written once and persists across every turn (the surrounding software resends it with every call—the model itself, remember, retains nothing). The user message carries the ask of the moment—this question, this ticket, this file. And assistant messages are the model’s own replies, which accumulate as the conversation’s history; usefully, you can also write assistant messages yourself, planting words in the model’s mouth as a way of showing, rather than describing, what a good answer looks like. My sorting rule: if an instruction would have to be repeated on every single turn, it belongs in the system message; if it is specific to this one request, it belongs in the user message. Mixing these up costs you later—a rule restated in each user message survives only as long as every caller remembers to restate it. Figure 2.4 lays out the three roles and the statelessness that resends the whole stack on every call.

The single biggest lever is clarity, and after two sections of mechanics you can see why it works. The model continues text; a vague instruction leaves the ranked list broad, and the lottery happily roams whatever space you leave open. A precise instruction narrows the field before the dice roll. In practice this means preferring enforceable constraints to adjectives: “three to five sentences” beats “keep it short,” and “at most five bullets, each under twelve words” beats “be concise,” because the first of each pair can be checked and the second is a mood. It means stating what you do not want, since the model’s trained helpfulness tends toward overreach: “do not invent prices”; “if the customer asks for a refund, do not promise one.” And it means providing a fallback for the case where the task cannot be done: “if the answer is not in the provided text, say you do not have enough information.” Without that last line, a model that lacks the answer will do what it was trained to do, which is answer.
Here is the anatomy assembled, small enough to read at a glance:
You are a support-ticket triage assistant.
Classify the ticket below into exactly one of:
  billing, bug, feature-request, other.
Ticket: "The app crashes every time I open settings."
Respond with the single category word and nothing else.
Five lines, four jobs: a role that sets scope, an instruction with a closed set of allowed answers, the input data, and an output contract. The phrases doing the real work are the strict ones—“exactly one of,” the fixed list, “nothing else.” Run this and a capable model returns bug nearly every time.
Nearly. Suppose one run in twenty comes back as “Bug.” with a capital letter and a period, or as “This sounds like a bug in the settings screen.” Your parser chokes, and staring harder at the instruction reveals no flaw in it. The standard escalation is to add examples:
Ticket: "You charged me twice this month."  -> billing
Ticket: "Can you add dark mode?"            -> feature-request
Ticket: "The app crashes every time
         I open settings."                  ->
Prompting with instructions alone is called zero-shot; adding worked demonstrations like these is few-shot; and the model’s knack for picking up the pattern has its own name, in-context learning—the model adapts to your task from examples inside the prompt, with no retraining of any kind. What the examples teach is what the failure above shows was missing (format and register), plus a third thing instructions describe poorly: edge-case handling. There is an instructive research result here: much of the benefit of demonstrations comes from their structure—a consistent format, a visible set of labels—and survives even when some of the individual labels are wrong.9 Sewon Min et al., “Rethinking the Role of Demonstrations: What Makes In-Context Learning Work?,” EMNLP 2022. Demonstrations with randomly substituted labels retained much of the benefit of correctly labeled ones; the format and the label space carried a large share of the effect. The examples work as a stencil for the answer’s shape. Two or three well-chosen ones capture most of the available gain; each additional example costs tokens on every call, in an agent’s case at every step, for shrinking returns.
Know also what demonstrations will not buy: a task the model reasons about wrongly tends to stay wrong however many finished answers precede it. Demonstrating the reasoning itself is a different device, and it gets its own treatment in Chapter 4. The escalation path that falls out of all this is pleasantly simple: start zero-shot; add two or three examples when the output’s shape wobbles; look elsewhere when the problem is the content.
Output format deserves its own explicit instruction whenever anything downstream depends on it. For prose meant for humans, name the sections, their order, and the length bounds. For output a program will parse, say the shape plainly—and understand that an instruction is a request, not a guarantee. The model can honor “respond with the single category word and nothing else” a thousand times and then, on run one thousand and one, wrap the word in a courteous sentence. Where parsing matters, the request can be upgraded to a contract, and that upgrade is the subject of the next section.
A word on personas, the most folkloric corner of prompting. Telling the model who to be—“you are a senior security reviewer,” “you write like a field guide”—reliably shapes voice, register, and scope, and for open-ended writing that is often exactly the lever you want. The folklore goes further and says a persona also makes answers more accurate: tell it to be an expert and it becomes one. The research picture is much less flattering: on factual and analytical tasks, simple personas show mixed and often negligible effects on capable models.10 Mingqian Zheng et al., “When ‘A Helpful Assistant’ Is Not Really Helpful: Personas in System Prompts Do Not Improve Performances of Large Language Models,” Findings of EMNLP 2024; PromptHub’s survey “Role-Prompting: Does Adding Personas to Your Prompts Really Make a Difference?” collects this and related studies. Elaborate, domain-matched personas have shown gains in some settings; a bare “you are an expert” generally has not. Use personas to set voice and boundaries; use instructions, examples, and genuine reasoning support for correctness.
Two placement habits complete the toolkit. First, when a task has several parts, spell them out as ordered steps—“first list the company names, then the people, then the recurring themes”—instead of gesturing at the whole (“extract the entities”). Explicit steps improve the output and, just as valuable, tell you which step failed when one does; you will meet this instinct again, grown up, when agents decompose whole projects in Chapter 4. Second, position matters. When a prompt opens with pages of material—a document, a transcript, a pile of tool results—put the instruction after the pile, and restate the one load-bearing rule near the end. Both halves of the reason are already yours: the model is a continuer, so a prompt that ends mid-document invites a continuation of the document rather than the task; and the desk’s edges stay sharp while its middle sags, so the final lines sit where recall is strongest. The last thing the model reads should be the thing you most need it to do.
I will not pretend any of this adds up to a science. Prompts are empirical objects: two phrasings you regard as identical can behave differently, and a prompt that works today can drift when the model behind it is upgraded. Treat prompts the way you treat code—versioned, tested, re-tested after every model change; Chapter 16 builds the apparatus. And hold on to the reframing this section has been steering toward. In an agent, no one types the final prompt. The system message is written once; the tool definitions are injected by machinery; the history accumulates turn by turn; retrieved documents and tool results are slotted in at runtime by code. Every principle above still applies—someone still chooses what the model reads—except that the someone becomes a program you write. Deciding, step after step, what earns a place on the desk is a large enough problem to carry its own name, context engineering, and Part III of this book is devoted to it. But Part III is a long way off, and the nearer gap is at hand: an instruction can only request a format. The next section shows how to guarantee one.
Structured Output and Function Calling
Chapter 1 called function calling the bridge from text to action and promised that this chapter would supply the mechanism. This section keeps the promise, and the place to start is the question of who reads the model’s output. As long as a human reads it, phrasing can wander freely; people forgive. The moment a program reads it, wandering breaks things—and everything an agent does depends on programs reading model output.
Feel the problem before we solve it. Suppose your code asks the model to pull two facts out of a customer email—the customer’s name and the order total—so it can write them into a database. Three runs, three answers, every one of them correct as prose:
Name: Ada, Total: $42
The customer is Ada Lovelace and she spent forty-two dollars.
Happy to help! Ada's order total is $42.00 (invoice #1041).
Before reading on, sketch the parsing code that handles all three. Whatever you wrote for the first breaks on the second; whatever handles the second trips on the third’s parenthesis; and tomorrow brings a fourth phrasing, because the lottery of two sections ago owes you no consistency. That is the root problem: natural language has enormous surface variability, and nothing obliges the model to phrase the same fact the same way twice. A program cannot consume possibilities. It needs a contract—a fixed shape the output is guaranteed to fit.
The standard contract is JSON (a simple, universal text format for nested key–value data), with its shape pinned down by a schema: a declaration of which fields exist, what type each holds, which are required, and what values are allowed. For the extraction task, in pseudocode—each vendor’s exact syntax differs:
{ name:     string,                       required
  total:    number,                       required
  currency: one of "USD" | "EUR" | "GBP",
  no other fields permitted }
An answer that fits this contract deserializes straight into a data structure the rest of your program already understands: the fields are where the code expects them, the total is a number, and the courteous sentence about invoice #1041 never happens.
How the model is made to comply matters more than it first appears, because there are two grades of guarantee and they sound alike. The weaker grade is asking: format instructions in the prompt, often backed by an API flag (commonly called a “JSON mode”) that guarantees the output at least parses as JSON. Parsing is a low bar. The model can still omit a required field, invent an extra one, or put a string where the number goes—syntax guaranteed, shape merely hoped for. The stronger grade is constrained decoding, and you already own the picture it needs. Every token, recall, is chosen from a ranked list by a draw. Constrained decoding compiles your schema into a filter that runs at every single step, striking from the list each token that would violate the schema before the draw is made. If the schema says a number comes next, no letter can win; if the field list is closed, no invented field can begin. The model chooses freely among valid continuations and cannot emit an invalid one—conformance is enforced in the machinery rather than requested in the prompt. Providers ship this under names like “structured outputs” and “strict” tool modes; the price is a little decoding overhead and some limits on how elaborate the schema may be.
One boundary I want marked in ink: a guarantee about shape says nothing about truth. Constrained decoding promises that the form comes back filled in; whether it is filled in truthfully is a different question entirely. If the model does not know the order total, the schema will not make it confess ignorance—it will make it produce a well-typed number. A schema, misused, makes fabrication easier to consume, not rarer. So validation stays in your code regardless: ranges, cross-field rules, “does this customer ID actually exist.” The schema polices the format; you remain the auditor of the content.
Now point the same idea at actions. Function calling (interchangeably, tool calling) begins with you describing, alongside the prompt, a set of functions the model may request: each with a name, a natural-language description, and a schema for its arguments. The model never executes anything. It has no hands; it only writes. What it can do, when it judges an action useful, is emit a structured request instead of prose—a small object naming a function and supplying arguments that fit the schema—and then stop and wait. The exchange runs like this (schematically; wire formats vary by provider):
1. you   -> model : the user's question + the list of tool definitions
2. model -> you   : { call: "get_weather", arguments: { city: "Paris" } }
3. your code      : runs the real get_weather("Paris")
4. you   -> model : the conversation so far + { result: { temp_c: 18 } }
5. model -> you   : "It's about 18 degrees in Paris right now."
                    (or another tool call, and the cycle repeats)
Two properties of this exchange—which Figure 2.5 lays out as two lanes—deserve underlining. The first is the division of authority: the model proposes; your code disposes. Chapter 1 used that sentence in passing, and now you can see it is literal. Every side effect in the system happens at step 3, inside ordinary code you wrote, where you can log it, test it, restrict it, or refuse it; the model’s entire contribution is a data structure expressing a wish. The second is that the exchange has two model calls at minimum, and the second one is where beginners stumble: the classic first bug is to execute the tool and hand its raw result to the user, when the result must instead go back to the model (step 4)—the model alone knows why it asked and what to do next. (And when you compose that step-4 message, return the few fields the model needs rather than the whole API blob; every byte of the result lands on the desk.)
A tool definition, to make the other side concrete (pseudocode again):
name:        create_ticket
description: Open a support ticket. Use when the user reports a
             problem that needs human follow-up.
arguments:   { title:    string,                        required
               severity: one of "low" | "med" | "high", required
               body:     string }
This definition—name, description, argument schema—is everything the model will ever know about your tool, and the description field is the piece I most want you to stare at, because it is the one newcomers underrate. The decision of whether and how to call create_ticket is made from this definition alone—there is no source code to consult, no wiki, no colleague to ask. Write it like API documentation for a capable new hire on their first morning: what the tool does, when to reach for it, when its neighbor is the better choice. When a model misuses a tool, or ignores one that would have helped, the description is the first suspect—ahead of the model. Designing the tools themselves, their number, granularity, and error messages, is a craft that gets its own chapter (Chapter 5).
Reality will exercise the unhappy paths, so plan for them. The model may emit arguments that fail validation, name a tool that does not exist, or make several calls in one turn—your handler should expect zero, one, or many. The recovery that works surprisingly well is to feed the failure back as data: return a structured error message as the tool result (“no such tool create_tickets; available tools are …”) and let the model read it and correct course on its next turn. Cap those retries with a hard budget, after which the run fails loudly; a stubborn confusion must never be allowed to loop at your expense. Chapter 18 builds this instinct into a discipline.
A closing caution, the one this section must post before handing you the bridge: well-formed is a statement about syntax, and safe is a statement about consequences. A flawlessly schema-conformant call to delete_account still deletes the account. Whether it should run—authorization, confirmation, limits—is your runtime’s decision to make at step 3, and Chapters 12 and 17 are about making it well. With that caution posted, the bridge is in place. Everything this book calls a “tool” from here on is exactly this mechanism, and an agent—as Chapter 1 said and Chapter 3 will finally build—is this request–execute–return exchange run in a loop. One piece of preparation remains: an honest map of the ways the engine fails.
Limitations and Failure Modes
Careful engineers keep two lists about any component they depend on: what it does well, and how it fails. This chapter has mostly been the first list. This section is the second, and it matters more than its length suggests, because every guardrail, evaluation, and verification pattern in the later parts of this book exists on account of an entry here. Two framing notes before the list. These are properties of the current generation of models—some will soften as training methods improve, and none, at the time of writing, is solved; where your models stand is something to verify, and this book will keep showing you how. And most of the entries follow directly from what the engine is: a plausibility machine shaped by human preference has characteristic ways of being wrong, and they respond to engineering, rarely to sterner wording in the prompt.
The first entry you have already met in principle: hallucination, the field’s term for output that is fluent, specific, confident, and wrong—an invented citation, a function that does not exist, a plausible date on which nothing happened. The mechanism was set out at the start of this chapter: when the model lacks a fact, the machinery produces the most plausible-looking string where the fact should be, because producing plausible strings is the whole of what it does. What makes hallucination operationally dangerous is the delivery: the fabricated answer arrives in exactly the same assured tone as the correct one. Tone carries no information about truth—you cannot hear the difference, and in any useful sense neither can the model. One analysis sharpens the point uncomfortably: we graded these systems into guessing, because training and benchmarks alike reward a confident attempt over an admission of uncertainty, exactly as a multiple-choice exam rewards the student who never leaves a blank.11 Adam Tauman Kalai et al., “Why Language Models Hallucinate” (2025), arXiv:2509.04664. The paper argues such fabrications “originate simply as errors in binary classification” during training and persist because “language models are optimized to be good test-takers, and guessing when uncertain improves test performance.” Worse, fabrications recruit reinforcements: once a false claim stands in the transcript, the model—conditioning, as always, on everything before it—tends to elaborate consistently on top of it, a pattern known as hallucination snowballing.12 Muru Zhang et al., “How Language Model Hallucinations Can Snowball” (2023), arXiv:2305.13534. Models that had been led to commit to a wrong claim went on to generate false supporting detail that they could, when asked separately, correctly identify as false.
The second entry defeats the intuition you would most like to keep: that capability is smooth—that a system this good at hard things must be at least as good at easy ones. You met the counterexample in miniature earlier in this chapter: an engine that solves a genuinely difficult problem in one breath and cannot reliably count the letters in a word in the next. The pattern generalizes, and it has earned a memorable name: the jagged frontier. In a preregistered field experiment (one whose analyses were committed in advance, so the findings could not be cherry-picked), several hundred consultants worked realistic tasks with and without model assistance. On tasks inside the frontier of the model’s competence, the assisted group completed measurably more tasks, faster, at higher rated quality. On one task deliberately selected to sit just outside the frontier, the assisted group was nineteen percentage points less likely to reach the correct answer.13 Fabrizio Dell’Acqua et al., “Navigating the Jagged Technological Frontier,” Harvard Business School Working Paper 24-013 (2023). The preregistered experiment enrolled 758 consultants; inside-frontier gains were 12.2% more tasks completed, 25.1% faster completion, and over 40% higher rated quality, against a 19-percentage-point accuracy deficit on the task designed to fall outside the frontier. The paper coined the term. Two lessons ride on that result. The frontier’s edge is invisible from where you stand—the failed task did not look harder; the researchers chose it precisely because it looked comparable. And competence next door proves nothing about competence here: the only reliable way to learn whether your model handles your task is to test your model on your task. That sentence returns in Chapter 16, where it grows into a discipline.
Third, and briefly: the model is sensitive to phrasing in ways no specification would tolerate. Reorder two clauses, swap a synonym, reformat a list, and the answer can change, because two prompts you consider equivalent are simply two different token sequences to the machine. This is the mechanical reason the previous section told you to treat prompts as empirical objects—tested like code, and re-tested when anything upstream changes the words that reach them.
Fourth comes sycophancy, the model’s bias toward telling you what you appear to want to hear. Run the experiment yourself. Ask a model a factual question it answers correctly; then reply, “I don’t think that’s right.” With disquieting regularity the model apologizes and abandons the correct answer—no new evidence offered, none requested. The trail leads back, at least in part, to post-training: models are tuned toward answers human raters prefer, raters often enough prefer agreement and flattery, and the model learned the lesson well.14 Mrinank Sharma et al., “Towards Understanding Sycophancy in Language Models,” Anthropic (2023; published at ICLR 2024). The study documents sycophantic behavior across several frontier assistants and traces it in part to human preference judgments that favor agreeable responses. Sycophancy bites hardest exactly where you would most like to lean on the model: checking work. “Are you sure?” is weak verification, because the model tends to ratify whatever frame the question hands it—push skeptically and it caves, ask approvingly and it endorses. When this book later insists that a real verifier beats self-judgment (Chapter 4) and that a model used as a judge must itself be validated (Chapter 16), sycophancy is a large part of the reason.
Fifth: exact computation. A next-token predictor contains no calculator, and earlier in this chapter you watched even the number system dissolve into arbitrary token chunks. Multi-digit arithmetic, precise counting, long chains of exact deduction—these wobble, and when they wobble mid-chain the model does not stop; it continues fluently from the wrong intermediate value. The remedy is architectural and cheap: route exact work to something exact—a calculator, a database, executed code—and let the model orchestrate rather than compute. Chapter 5 makes this a design principle.
Sixth, an entry I will only preview because Chapter 17 treats it in earnest: the model reads instructions and data in one undifferentiated stream, and it cannot reliably tell them apart. Text that merely passes through the context—a fetched web page, an email, a tool result—can steer the model’s behavior if it is shaped like an instruction. The attack family is the one Chapter 1 named in passing, prompt injection, and it earns its place on this list for one reason: it is a property of the engine, present before you have written a single line of agent code. (Nondeterminism and stale knowledge, the remaining usual suspects, had their treatment earlier in this chapter.)
Taken one at a time, these are annoyances with workarounds. The reason they deserve permanent residence in your head is what happens when you chain them. Chapter 1’s compass ran this arithmetic once, as an assertion; this is where it is defended, and where later chapters (Chapters 16 and 18 among them) will point back rather than re-derive it. An agent is a chain of dependent steps: each model call reasons over the results of the calls before it. Suppose each step succeeds with probability p, independently, and a task needs n steps; the whole run then succeeds with probability roughly pn. Now put honest numbers in. A per-step reliability of 95% sounds excellent, and in a demo it is. Across a twenty-step task: 0.9520 ≈ 36%. Across thirty steps at a slightly worse 92%: 0.9230 ≈ 8%. The per-step number would have earned a bonus; the end-to-end number is a coin you would never bet on. Exponentials do not negotiate. Figure 2.6 draws the decay.

And the clean multiplication is the optimistic version, because it assumes the steps fail independently. They do not. An agent’s errors land in its own transcript, where—by the logic of this entire chapter—they become context that conditions everything after. Hallucination snowballing was this pattern applied to facts; it holds for actions too. A run that has started to go wrong is, from that point forward, reasoning over a partially wrong desk, and its per-step error rate drifts upward as the run lengthens; researchers measuring long tasks report exactly this signature, reliability decaying with task length faster than independence would predict.15 The self-conditioning effect—per-step accuracy declining as a model’s own earlier errors accumulate in its context—is reported in work on long-horizon execution, e.g. Sinha et al., “The Illusion of Diminishing Returns: Measuring Long Horizon Execution in LLMs” (2025), arXiv:2509.09677. A confused agent stays confused, and left alone, it gets more so.
If the arithmetic is merciless, it is also clarifying: it tells you exactly where the levers are, and there are three. Shrink n—fuse steps, precompute what can be precomputed, and push bulk mechanical work into ordinary code, which does not roll dice (Chapter 5 shows how far this goes). Raise the effective p—verify at each step and recover on failure, so that an error costs a retry instead of the run; that machinery fills Part V. And cut the price of dying—checkpoint, so that when a run does fail it resumes from the last good state instead of from zero (Chapter 18). What you cannot do is ignore the exponent and hope. Per-step accuracy is a ceiling, not a forecast.
The engine is now mapped, which is all a map can promise. In one chapter you have collected a predictor that continues text and holds no plan in reserve; a desk that is finite, expensive, swept between calls, and sharpest at its edges; a lottery that writes one token at a time and never promises the same text twice; a steering discipline that works entirely in text; a bridge that turns text into checked, executable requests; and a failure catalog whose master entry is the exponent. None of it required mathematics beyond arithmetic, and all of it becomes load-bearing immediately: Part II takes this engine—brilliant, forgetful, overconfident, dice-driven—and puts it in a loop.